Python aiohttp Concurrent Requests with asyncio and Semaphore
Use aiohttp with asyncio to make concurrent HTTP requests, and cap the number of in-flight requests with a semaphore.
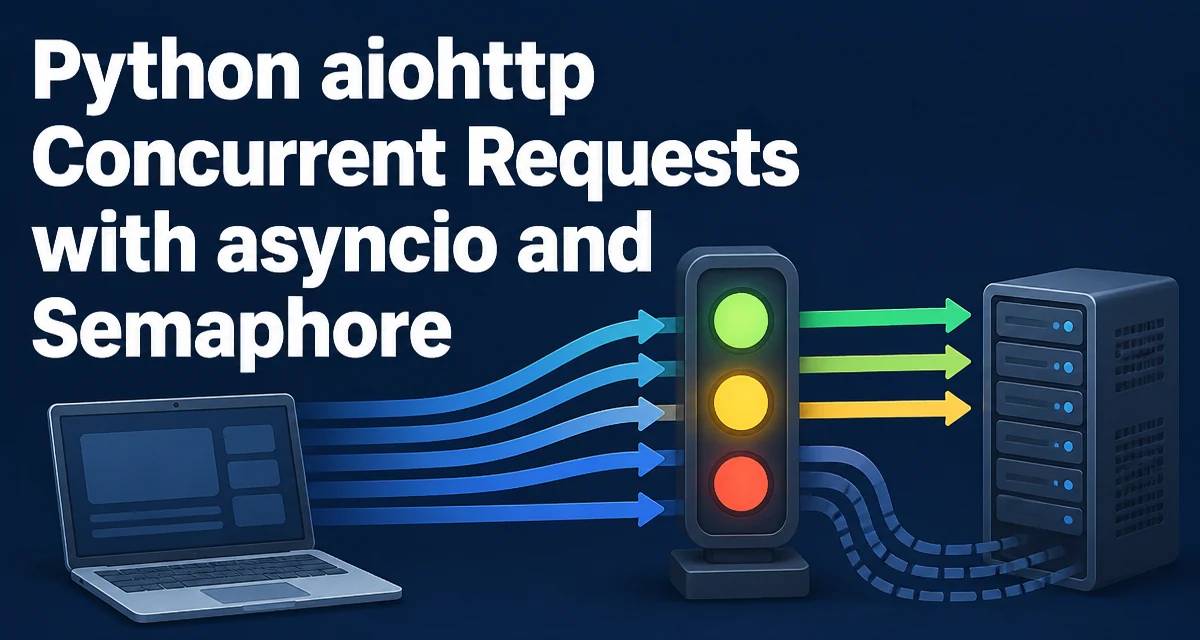
When you need to make many HTTP requests from a Python program, aiohttp is a natural choice because it works with asyncio. Using a semaphore lets you control how many requests run at once, preventing overload of the target server and your own process.
Why Use aiohttp for Concurrent Requests
aiohttp provides an asynchronous HTTP client that integrates directly with asyncio. Unlike requests, which blocks the event loop, aiohttp lets you issue many requests concurrently without threading. This is particularly useful for scraping, API client libraries, or batch operations where you need to fetch or send data to many endpoints.
The core pattern is to create a session, define an async function that performs a request, and then schedule multiple invocations of that function with asyncio.gather. However, launching hundreds of requests at once can exhaust file descriptors, saturate the network, or trigger rate limits on the server. A semaphore is the standard asyncio primitive to cap the number of concurrent operations.
The Problem with Unbounded Concurrency
If you simply gather a large list of tasks, asyncio will start all of them immediately. Each task will attempt to open a connection and send a request. With a few dozen requests this might be fine, but with thousands, you can run into connection timeouts, memory pressure, and server-side throttling. The event loop can handle many pending tasks, but the underlying network stack and the remote server have limits.
A semaphore solves this by allowing only a fixed number of coroutines to proceed past a given point. In the context of aiohttp, you acquire the semaphore before sending a request and release it after the response is processed. This bounds the number of in-flight requests.
Using asyncio.gather with aiohttp
Here is a basic example without a semaphore. It creates a session, defines a fetch function, and gathers a list of URLs.
import asyncio
import aiohttp

async def fetch(session, url):
    async with session.get(url) as response:
        return await response.text()

async def main():
    urls = ["https://example.com"] * 100
    async with aiohttp.ClientSession() as session:
        tasks = [fetch(session, url) for url in urls]
        results = await asyncio.gather(*tasks)
    print(len(results))

asyncio.run(main())
This works, but it starts all 100 requests at once. For a small number of URLs that is acceptable, but it does not scale well. The gather function collects results in the order of the input list, but it does not limit concurrency.
Introducing Semaphore to Limit Concurrency
To limit the number of concurrent requests, create an asyncio.Semaphore with a desired limit and acquire it inside the fetch function. The semaphore must be shared across all tasks. Here is the same example with a limit of 10 concurrent requests.
import asyncio
import aiohttp

async def fetch(session, url, semaphore):
    async with semaphore:
        async with session.get(url) as response:
            return await response.text()

async def main():
    urls = ["https://example.com"] * 100
    limit = 10
    semaphore = asyncio.Semaphore(limit)
    async with aiohttp.ClientSession() as session:
        tasks = [fetch(session, url, semaphore) for url in urls]
        results = await asyncio.gather(*tasks)
    print(len(results))

asyncio.run(main())
The async with semaphore: block ensures that the semaphore is acquired before the request starts and released after the response context exits. This is the idiomatic way to use a semaphore with aiohttp. The limit should be chosen based on the target server's capacity and your own system's resources. A common starting point is 10–20 for public APIs, but you should test and adjust.
Handling Errors in Concurrent Requests
When you gather many tasks, an exception raised by one task propagates out of asyncio.gather by default, even if other tasks would have succeeded. You have several options. One is to catch exceptions inside the fetch function and return a default value. Another is to use asyncio.gather with return_exceptions=True and inspect the results.
async def fetch(session, url, semaphore):
    async with semaphore:
        try:
            async with session.get(url) as response:
                return await response.text()
        except aiohttp.ClientError as e:
            return f"Error: {e}"
This approach keeps the task from failing, but it hides the exception type. If you need to retry failed requests, you can catch the exception and schedule a retry with a backoff. The semaphore still applies to the retry because it is inside the same function.
Setting Timeouts and Retries
Aiohttp requests can hang indefinitely if the server does not respond. You should set a timeout on the session or on individual requests. The ClientTimeout class allows you to specify total, connect, and read timeouts.
timeout = aiohttp.ClientTimeout(total=30)
async with aiohttp.ClientSession(timeout=timeout) as session:
    # ...
For retries, wrap the request in a loop. The semaphore is held during the entire retry sequence, so you are still limiting the number of concurrent request operations, including retries.
async def fetch_with_retry(session, url, semaphore, retries=3):
    async with semaphore:
        for attempt in range(retries):
            try:
                async with session.get(url) as response:
                    return await response.text()
            except aiohttp.ClientError:
                if attempt == retries - 1:
                    raise
                await asyncio.sleep(2 ** attempt)
Performance and Resource Considerations
The semaphore controls the number of concurrent requests, but it does not control the size of the task list. If you have 10,000 URLs, you still create 10,000 tasks. Each task is lightweight, but they all hold a reference to the session and the semaphore. This is usually acceptable, but for very large lists you might want to use a producer–consumer pattern with a queue to avoid creating all tasks at once.
Another consideration is connection pooling. Aiohttp's ClientSession maintains a connection pool. The default TCPConnector limits total simultaneous connections, not necessarily per-host. If your semaphore limit is higher than that value, some requests can wait for a free connection. You can adjust the pool with a configured TCPConnector, but be careful not to exceed system limits.
Memory usage is also affected by the response bodies. If you are downloading large files, consider streaming the response and writing to disk instead of reading the entire body into memory.
Production Considerations: Connection Pooling and Graceful Shutdown
In a production script, you should reuse a single ClientSession for all requests and close it properly. The async with pattern handles this. If you are running a long-lived service, you may want to create the session at startup and close it during shutdown.
The semaphore limit should be configurable, perhaps via an environment variable, so you can adjust it without changing code. Monitor the number of in-flight requests and the response times to find the optimal value.
When the event loop is interrupted, asyncio will cancel pending tasks. For a simple script this is usually fine. For a service, implement a graceful shutdown that stops accepting new tasks, waits for in-flight work to finish or cancels it, and closes the session.
Using a semaphore with aiohttp is a straightforward way to add controlled concurrency to your Python applications. It gives you the performance benefit of async requests without the risk of overwhelming the target server or your own system.
Try matching browser tools
All toolsSmall utilities that fit Python work — they run entirely in this browser tab, so nothing you paste leaves your device.
Related Python guides
All Python guidesPython iter(): How the Built-in Function Works
Explains Python's iter() built-in: how it creates iterators, the two-argument sentinel form, custom iterator classes, and common edge cases.
Python Pika: Queues, Exchanges, Routing Keys, and Acknowledgements
Learn how to use Python's Pika client with RabbitMQ: declare queues and exchanges, publish with routing keys, consume messages, and handle acknowledgements reliably.
Python Kafka: kafka-python vs Confluent Client
python kafka python vs confluent kafka: Compare kafka-python and Confluent Kafka Python clients: API differences, performance, feature coverage, and when to choose eac...
Python Kafka Offsets, Partitions, and Manual Commits
Learn how Kafka offsets and partitions work and how to manually commit offsets in Python consumers with kafka-python and confluent-kafka. Covers sync vs async commits, rebalances, and seeking.
More in Python
All Python guidesThe guides filed next to this one in Python, in library order.