Java HashMap: How It Works and When to Use It
Understand Java HashMap's internal structure, performance characteristics, and common pitfalls to write efficient, predictable code.
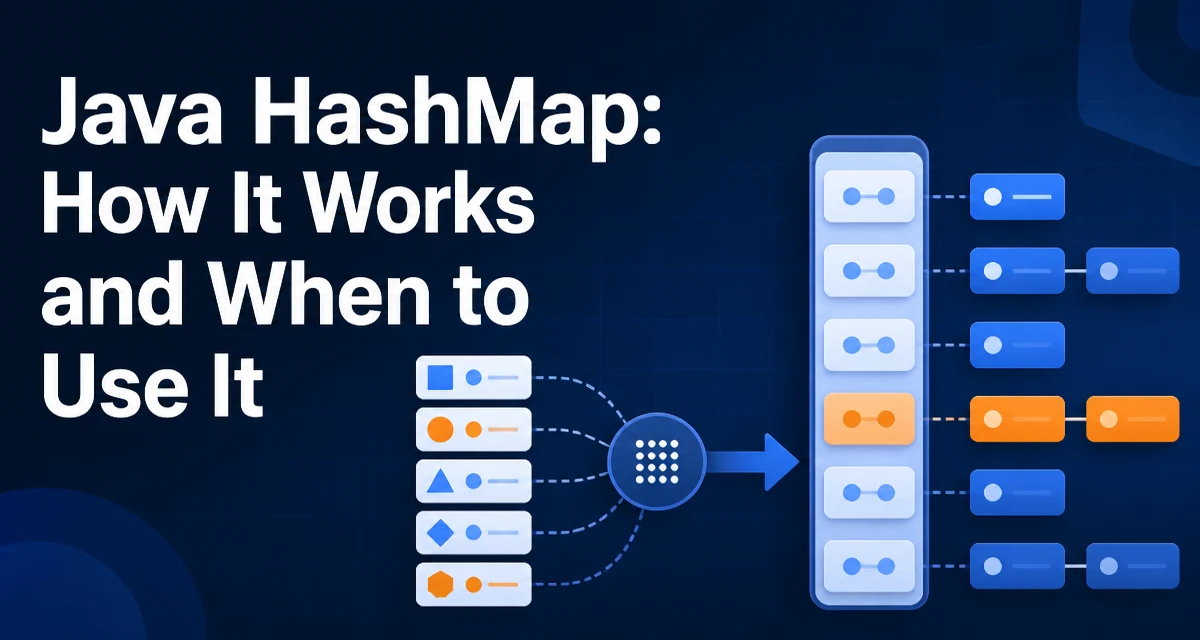
Java HashMap is the most widely used Map implementation in Java, but its behavior under the hood directly affects performance and correctness. The class stores key-value pairs in an array of buckets, using a hash function to determine where each entry lands. This design gives average constant-time lookup, but the details matter when you are dealing with large datasets, custom objects, or concurrent access.
How HashMap Stores Entries
Internally, a HashMap maintains an array of nodes, often called buckets. When you call put(key, value), the map computes key.hashCode() and applies a secondary hash to spread bits more evenly. The result is used to select a bucket index. If two different keys map to the same bucket, a collision occurs, and the entries are stored in a linked list within that bucket. Since Java 8, when a bucket becomes long enough and the table is large enough, the list is converted to a red-black tree to keep lookup time at O(log n) instead of O(n). This conversion is an implementation detail, but it explains why worst-case performance is no longer linear for very large collision chains.
The following example shows a basic usage pattern:
Map<String, Integer> scores = new HashMap<>();
scores.put("alice", 90);
scores.put("bob", 85);
Integer aliceScore = scores.get("alice"); // 90
The map uses the String class's hashCode() implementation, which is well-distributed. For custom classes, you must provide a proper hashCode() and equals() pair, as discussed next.
Understanding the hashCode and equals Contract
The behavior of HashMap depends entirely on the hashCode() and equals() methods of its keys. The contract states that if two objects are equal according to equals(), they must have the same hashCode(). Violating this rule breaks the map's ability to find entries. For example, consider a Person class that overrides equals() but not hashCode(). Two instances with the same name would be equal but produce different hash codes, so get() would likely return null even after put().
A correct implementation looks like this:
public class Person {
    private final String name;

    public Person(String name) {
        this.name = name;
    }

    @Override
    public boolean equals(Object o) {
        if (this == o) return true;
        if (!(o instanceof Person)) return false;
        Person p = (Person) o;
        return name.equals(p.name);
    }

    @Override
    public int hashCode() {
        return name.hashCode();
    }
}
When you use a mutable object as a key, the hash code can change after the entry is inserted. If the object's state changes, the bucket index no longer matches the stored entry, making it unreachable. This is a common source of subtle bugs. Prefer immutable keys, such as String, Integer, or custom immutable classes.
Performance Characteristics of HashMap
HashMap offers average O(1) time for put, get, and remove operations, assuming a good hash function and a reasonable load factor. The load factor controls when the map resizes its internal array. The default load factor is 0.75, meaning that when the number of entries reaches 75% of the capacity, the map doubles its capacity and rehashes all entries. This resize operation costs O(n) and can cause temporary latency spikes in applications that store many entries.
Choosing an initial capacity can reduce resizing overhead. If you know the approximate number of entries, create the map with that capacity divided by the load factor:
int expectedSize = 1000;
Map<String, Integer> map = new HashMap<>((int) (expectedSize / 0.75 + 1));
This avoids multiple resizes when the map grows. However, setting an excessively large capacity wastes memory, so balance is necessary.
The hash function itself also matters. Java's String.hashCode() is well-distributed, but a badly distributed hash code—for example, one that always returns the same value—forces many keys into the same bucket. On Java 8 and later, a very long bin can be converted to a tree, but for smaller maps or older JDKs, such a hash effectively turns the map into a linked list and operations become O(n). Always design hash codes to spread values across the integer range.
Concurrency: HashMap vs ConcurrentHashMap
HashMap is not thread-safe. If multiple threads modify the same HashMap without external synchronization, writes can corrupt its internal structure, causing lost entries and unpredictable behavior (including infinite loops in some older JDK versions). The java.util.Hashtable class is synchronized but uses a global lock, which serializes all access and hurts scalability. For concurrent use, ConcurrentHashMap is the recommended choice. It uses finer-grained locking and lock-free reads, so reads do not block and writes to different buckets can proceed without a global lock.
Consider this scenario:
Map<String, Integer> map = new ConcurrentHashMap<>();
// Safe for concurrent access from multiple threads
Even with ConcurrentHashMap, be aware that methods like putIfAbsent are atomic, but a sequence like if (!map.containsKey(key)) map.put(key, value) is not. Use computeIfAbsent or merge for atomic updates.
Common Pitfalls When Using HashMap
One frequent mistake is assuming iteration order. HashMap does not guarantee any order, and the order can change after resizing. If insertion order is required, use LinkedHashMap. If sorted order is needed, use TreeMap.
Null handling is another area of confusion. HashMap allows one null key and any number of null values, but ConcurrentHashMap does not permit null keys or values. This difference can cause unexpected NullPointerException when switching implementations.
Also, avoid using a mutable object as a key after it has been inserted. Even if the object's hashCode() is based on a mutable field, changing that field makes the bucket index no longer match, so the entry cannot be found or removed by key afterward. This can appear as a memory leak because the stale entry stays in the map.
Choosing Between HashMap and Other Map Implementations
HashMap is the best default when you need fast lookup and do not care about ordering. But other implementations may fit specific requirements better:
| Implementation | Ordering | Thread Safety | Use Case |
|---|---|---|---|
| HashMap | None | No | General-purpose key-value storage |
| LinkedHashMap | Insertion order | No | LRU caches, order-sensitive iteration |
| TreeMap | Sorted by key | No | Range queries, sorted iteration |
| ConcurrentHashMap | None | Yes | Concurrent access |
| EnumMap | Order of enum constants | No | Enum keys, compact and fast |
For example, an LRU cache can be built by overriding removeEldestEntry() in LinkedHashMap:
class LRUCache<K, V> extends LinkedHashMap<K, V> {
    private final int maxSize;

    public LRUCache(int maxSize) {
        super(16, 0.75f, true);
        this.maxSize = maxSize;
    }

    @Override
    protected boolean removeEldestEntry(Map.Entry<K, V> eldest) {
        return size() > maxSize;
    }
}
This approach gives O(1) access and automatically evicts the least recently used entry when the cache exceeds its limit.
Practical Example: Caching with HashMap
A common use of HashMap is to cache expensive computations. The following pattern uses computeIfAbsent, which computes and stores a value only when the key is absent:
public class RecordCache {
    private final Map<Integer, String> cache = new HashMap<>();

    public String getRecord(int id) {
        return cache.computeIfAbsent(id, this::loadRecord);
    }

    private String loadRecord(int id) {
        // Simulate a slow read or calculation.
        return "record-" + id;
    }
}
The mapping function passed to computeIfAbsent should not modify the same map while it is running. If the cache is accessed from multiple threads, use ConcurrentHashMap; its computeIfAbsent method is atomic and can be used without additional locking.
When using a cache, be mindful of memory usage. An unbounded HashMap can grow indefinitely, leading to OutOfMemoryError. Consider a bounded structure like the LinkedHashMap LRU cache shown earlier, or a dedicated caching library that supports expiration.
Handling Collisions with Custom Hash Functions
When you have control over the key class, you can improve hash distribution by using a custom hash function. For example, if your key class has an immutable integer field that tends to follow a predictable pattern, you can mix bits to avoid clustering:
@Override
public int hashCode() {
    int h = id;
    h ^= (h >>> 20) ^ (h >>> 12);
    return h ^ (h >>> 7) ^ (h >>> 4);
}
This is similar to the technique used in Java's HashMap for its internal spread. But for most cases, relying on the default hash of standard types is sufficient. Only implement custom hashing when profiling shows that collisions are a bottleneck.
Understanding Resize and Rehash Behavior
When the map resizes, it recalculates the bucket index for every existing entry. This is necessary because the array length changes, and the index depends on the length. The resize operation is expensive, but it is amortized over the insertions that trigger it. In a single-threaded environment, you can reduce resizes by setting a higher initial capacity. In a concurrent environment, resizing can cause temporary pauses, so pre-sizing a ConcurrentHashMap is even more important.
If you are storing a very large number of entries, consider using a specialized map like IntObjectHashMap from an external collections library, which avoids boxing and reduces memory overhead. However, the standard HashMap is sufficient for most applications.
Final Technical Consideration: Iterating While Modifying
Iterating over a HashMap while modifying it, except through the iterator's own remove() method, throws a ConcurrentModificationException. This is a fail-fast behavior designed to catch bugs early. For example:
Map<String, Integer> map = new HashMap<>();
map.put("a", 1);
map.put("b", 2);

for (String key : map.keySet()) {
    if (key.equals("a")) {
        map.remove(key); // Throws ConcurrentModificationException
    }
}
To remove entries during iteration, use the iterator directly:
Iterator<Map.Entry<String, Integer>> it = map.entrySet().iterator();
while (it.hasNext()) {
    Map.Entry<String, Integer> entry = it.next();
    if (entry.getKey().equals("a")) {
        it.remove();
    }
}
This rule applies to all fail-fast iterators in the Java Collections Framework. If you need concurrent modification, use ConcurrentHashMap, whose iterators are weakly consistent and do not throw this exception.