Python gather vs TaskGroup: Choosing the Right Concurrency API
Compare asyncio.gather and asyncio.TaskGroup in Python: error propagation, cancellation, and when to use each for structured concurrency.
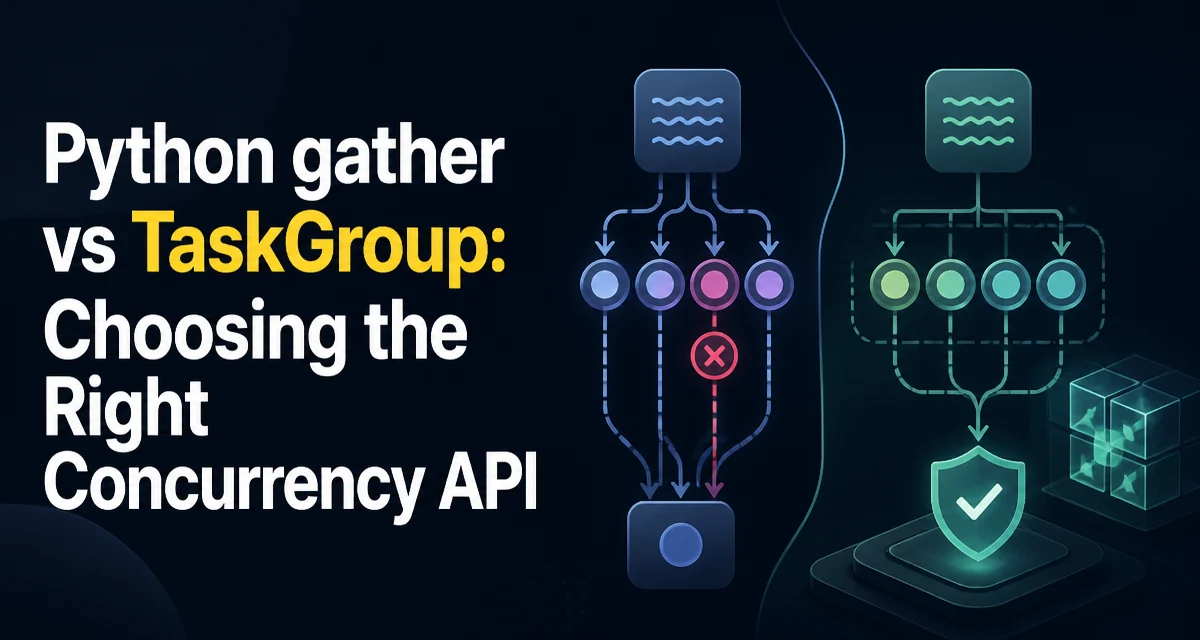
When you need to run multiple coroutines concurrently in Python, asyncio.gather has been the go-to helper for years. Python 3.11 introduced asyncio.TaskGroup, which implements structured concurrency and changes how you think about error handling and cancellation. The choice between gather and TaskGroup affects not just syntax but the behavior of your program when tasks fail or are cancelled.
The Core Difference Between gather and TaskGroup
asyncio.gather is a function that schedules multiple awaitables and returns a single future. In the normal success case, it collects results into a list, preserving the order of the input coroutines. asyncio.TaskGroup is a context manager that creates tasks and waits for all of them to complete before exiting the block. The key structural difference is that TaskGroup enforces a scope: you cannot leave the async with block until every task has finished, either normally or with an exception.
import asyncio

async def fetch(url):
    await asyncio.sleep(1)
    return f"data from {url}"

async def main_gather():
    urls = ["a.com", "b.com", "c.com"]
    results = await asyncio.gather(*(fetch(u) for u in urls))
    print(results)

async def main_taskgroup():
    urls = ["a.com", "b.com", "c.com"]
    async with asyncio.TaskGroup() as tg:
        tasks = [tg.create_task(fetch(u)) for u in urls]
    # After the block, all tasks have completed.
    results = [t.result() for t in tasks]
    print(results)
In the TaskGroup version, the block exits only after all tasks finish. This guarantees that no task is left running in the background when you proceed, which is a core tenet of structured concurrency. gather does not impose such a scope; you are responsible for ensuring that all tasks are awaited or cancelled before the program ends.
How Error Propagation Differs
gather by default propagates the first exception that occurs, but it does not cancel the other tasks. They continue running in the background, and their results or exceptions are silently ignored unless you set return_exceptions=True. This can lead to orphaned tasks that consume resources or produce side effects after an error has already been raised.
async def fail():
    await asyncio.sleep(0.5)
    raise ValueError("boom")

async def slow_ok():
    await asyncio.sleep(2)
    return "ok"

async def main():
    try:
        await asyncio.gather(fail(), slow_ok())
    except ValueError as e:
        print(f"Caught: {e}")
    # slow_ok() is still running here, but we don't await it.
With TaskGroup, the first task exception cancels all sibling tasks. The context manager waits for those cancellations to complete, then raises an ExceptionGroup containing the exceptions from the failed tasks. This prevents tasks from leaking and ensures that the scope is cleanly exited.
async def main():
    try:
        async with asyncio.TaskGroup() as tg:
            tg.create_task(fail())
            tg.create_task(slow_ok())
    except* ValueError as eg:
        print(f"Caught: {eg.exceptions}")
    # At this point, slow_ok() has been cancelled and cleaned up.
The except* syntax is required for ExceptionGroup, which TaskGroup raises when tasks fail. This is a notable shift from gather's simple except handling.
Cancellation Behavior: gather vs TaskGroup
gather does not automatically cancel tasks when one fails. If you want to cancel the remaining tasks, you must do it manually, often by wrapping each coroutine in a Task and calling cancel() in an exception handler. This is error-prone and easy to get wrong, especially when tasks have nested awaits.
TaskGroup handles cancellation as part of its design. If any task raises an exception, the group cancels all other tasks. If the outer coroutine is cancelled while inside the async with block, the group cancels all tasks and waits for them to finish before propagating the CancelledError. This makes cleanup deterministic and prevents tasks from being left in an indeterminate state.
async def main():
    async with asyncio.TaskGroup() as tg:
        tg.create_task(asyncio.sleep(10))
        tg.create_task(asyncio.sleep(10))
        # If an exception occurs here, both sleeps are cancelled.
For gather, you would need to manually track tasks and cancel them, which adds boilerplate and increases the chance of missing a path.
Code Structure and Readability
TaskGroup encourages a flatter, more explicit structure. You create tasks inside a block, and the block boundary clearly defines the lifetime of those tasks. This makes it easier to reason about where tasks start and where they are guaranteed to be finished. gather often leads to a one-liner that hides the complexity of task management, especially when you need to handle partial failures or cancellation.
# gather: results are collected, but error handling is implicit
results = await asyncio.gather(*coroutines, return_exceptions=True)

# TaskGroup: explicit task creation and result retrieval
async with asyncio.TaskGroup() as tg:
    tasks = [tg.create_task(coro) for coro in coroutines]
results = [t.result() for t in tasks]
The explicit version makes it clear that each task is a separate entity with its own result or exception. It also allows you to access individual tasks before the group completes, which is useful for progress reporting or partial cleanup.
When to Use gather and When to Use TaskGroup
Use gather when you have a fixed set of coroutines that are independent, and you want to collect their results in order without needing structured cancellation. On Python 3.10 or earlier, TaskGroup is unavailable, so gather is the practical choice for this pattern. For simple fan-out where failure of one task should not affect others, gather(..., return_exceptions=True) is a concise choice.
Use TaskGroup when you need structured concurrency: when tasks share a scope, when a failure should cancel siblings, or when you want to avoid orphaned tasks. It is the recommended approach for new code on Python 3.11+ because it makes error handling and cancellation explicit and safe. If you are building a library or framework that manages long-running tasks, TaskGroup provides a clearer contract for resource cleanup.
Performance and Overhead Considerations
Both gather and TaskGroup use the same underlying event loop and task machinery. The performance difference is negligible for typical I/O-bound workloads. TaskGroup may have a tiny overhead due to the context manager and exception group handling, but this is rarely measurable in real applications. The more significant cost is in code complexity: gather can lead to subtle bugs when tasks fail and are not cancelled, which can cause resource leaks or unexpected behavior under load. TaskGroup avoids these issues by design, making it the safer choice for production systems where reliability matters more than micro-optimizations.
When you need to run thousands of short tasks, the overhead of creating a TaskGroup per batch is minimal. The real bottleneck is usually the number of concurrent connections or I/O operations, not the API you choose. Focus on the semantic differences rather than performance when deciding between gather and TaskGroup.
Try matching browser tools
All toolsSmall utilities that fit Python work — they run entirely in this browser tab, so nothing you paste leaves your device.
Related Python guides
All Python guidesPython iter(): How the Built-in Function Works
Explains Python's iter() built-in: how it creates iterators, the two-argument sentinel form, custom iterator classes, and common edge cases.
Python Pika: Queues, Exchanges, Routing Keys, and Acknowledgements
Learn how to use Python's Pika client with RabbitMQ: declare queues and exchanges, publish with routing keys, consume messages, and handle acknowledgements reliably.
Python Kafka: kafka-python vs Confluent Client
python kafka python vs confluent kafka: Compare kafka-python and Confluent Kafka Python clients: API differences, performance, feature coverage, and when to choose eac...
Python Kafka Offsets, Partitions, and Manual Commits
Learn how Kafka offsets and partitions work and how to manually commit offsets in Python consumers with kafka-python and confluent-kafka. Covers sync vs async commits, rebalances, and seeking.
More in Python
All Python guidesThe guides filed next to this one in Python, in library order.