KMeans vs DBSCAN: Clustering with Python and scikit-learn
Compare KMeans and DBSCAN for clustering with Python and scikit-learn. Understand their assumptions, implement each algorithm, choose parameters, and decide which fits your data.
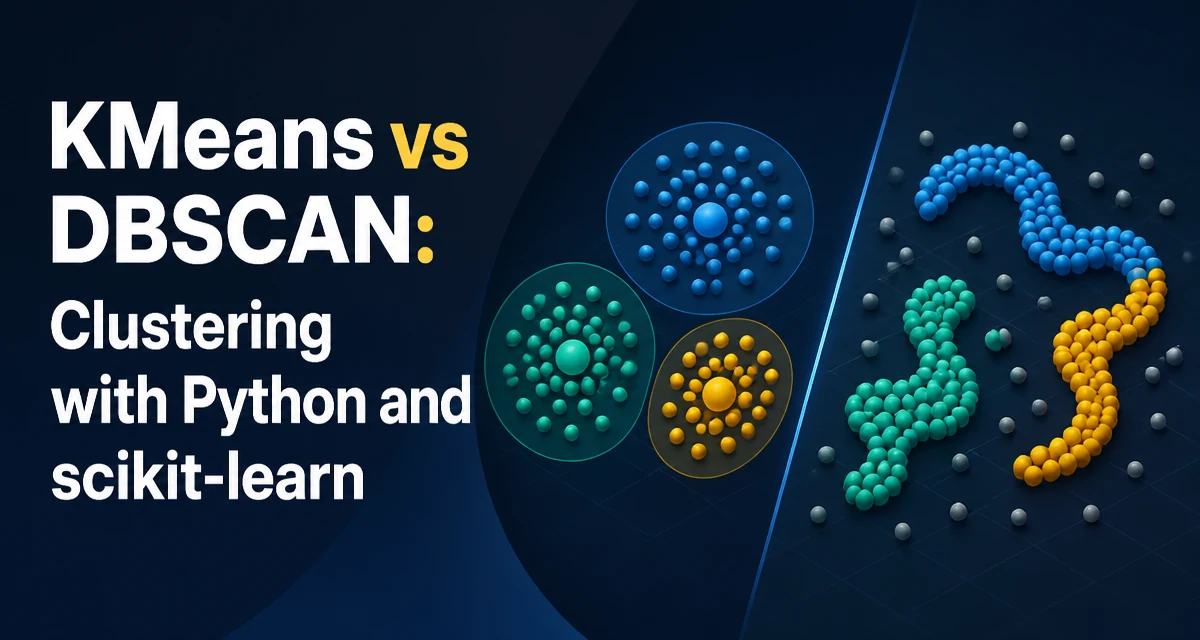
When you need to group unlabeled data, scikit-learn offers two widely used clustering algorithms: KMeans and DBSCAN. Both are part of the sklearn.cluster module, but they make very different assumptions about the structure of your data. Understanding those assumptions is the key to choosing the right algorithm for a given dataset.
What KMeans and DBSCAN Assume About Your Data
KMeans partitions data into n_clusters groups by assigning each point to the nearest centroid. It then iteratively moves the centroids to minimize the within-cluster sum of squares. This works well when clusters are roughly spherical, similar in size, and well separated. It can fail when clusters are elongated, nested, or have very different densities.
DBSCAN groups points based on density. It defines a neighborhood around each point using eps and requires a minimum number of points (min_samples) to form a dense region. Points that are not reachable from any dense region are labeled as noise. This allows DBSCAN to discover clusters of arbitrary shape and to identify outliers, which KMeans cannot do.
The practical consequence is that KMeans always assigns every point to a cluster, even if the point is far from all centroids. DBSCAN can leave points unassigned as noise, which is often desirable when your data contains outliers.
Implementing KMeans with scikit-learn
Using KMeans in scikit-learn is straightforward. You instantiate the estimator, fit it to your data, and read the labels_ attribute.
from sklearn.cluster import KMeans
import numpy as np

X = np.array([[1, 2], [1, 4], [1, 0],
              [10, 2], [10, 4], [10, 0]])

kmeans = KMeans(n_clusters=2, random_state=42)
kmeans.fit(X)
print(kmeans.labels_)
print(kmeans.cluster_centers_)
The n_clusters parameter controls the number of clusters and should be set before fitting. The random_state parameter ensures reproducible results because KMeans initialization is stochastic. After fitting, cluster_centers_ contains the final centroid coordinates, and inertia_ gives the sum of squared distances from each point to its nearest centroid, which you can use in an elbow analysis.
KMeans is sensitive to feature scaling. If one feature has a much larger range than another, that feature can dominate the distance calculation. Standardizing your data before applying KMeans is a good default.
Implementing DBSCAN with scikit-learn
DBSCAN requires two parameters: eps and min_samples. The eps value defines the radius of the neighborhood around each point, and min_samples is the number of points required to form a dense region.
from sklearn.cluster import DBSCAN
import numpy as np

X = np.array([[1, 2], [2, 2], [2, 3],
              [8, 7], [8, 8], [25, 80]])

dbscan = DBSCAN(eps=3, min_samples=2)
dbscan.fit(X)
print(dbscan.labels_)
Points with label -1 are considered noise. Unlike KMeans, DBSCAN does not require you to specify the number of clusters. It discovers clusters based on density. However, choosing eps is not trivial. A common approach is to plot the distance to the k-th nearest neighbor for each point and look for an elbow in the curve. The min_samples value is often set to twice the number of features, but you should adjust it based on your domain knowledge.
DBSCAN also relies on distance calculations, so feature scaling is equally important. Without scaling, eps can be dominated by features with larger ranges.
Choosing Between KMeans and DBSCAN
The decision depends on the shape and quality of your data. Use KMeans when:
- You know the number of clusters in advance.
- Clusters are roughly spherical and similar in size.
- You need a hard assignment for every point, including outliers.
- You want a fast, scalable algorithm for large datasets.
Use DBSCAN when:
- You do not know the number of clusters.
- Clusters have arbitrary shapes or varying densities.
- Your data contains noise that should be identified.
- You want to avoid committing to a fixed number of clusters.
The following table summarizes the key differences:
| Criterion | KMeans | DBSCAN |
|---|---|---|
| Assumed cluster shape | Roughly spherical | Arbitrary |
| Number of clusters | Set with n_clusters | Discovered from density |
| Outlier handling | Forced into clusters | Labeled as noise |
| Main parameters | n_clusters | eps, min_samples |
| Complexity | O(n·k·d) per iteration | O(n log n) with spatial index; O(n²) worst case |
For a dataset with well-separated, convex clusters, KMeans is faster and easier to tune. For real-world data with irregular shapes and outliers, DBSCAN often produces more meaningful groupings.
Preprocessing and Scaling for Both Algorithms
Both algorithms use Euclidean distance by default. If your features have different scales, the distance metric becomes biased. Standardization ensures each feature contributes equally.
from sklearn.preprocessing import StandardScaler

scaler = StandardScaler()
X_scaled = scaler.fit_transform(X)
Apply scaling before fitting either model. For DBSCAN, scaling also affects the interpretation of eps: after scaling, choose eps in standardized units rather than original feature units. For KMeans, scaling prevents features with large numeric ranges from dominating the centroid calculation.
If your data contains categorical variables, neither algorithm works directly. You would need to encode them appropriately, but the distance-based nature of both algorithms makes them better suited for continuous numerical features.
Evaluating Clustering Results
Choosing n_clusters for KMeans or eps for DBSCAN requires a way to measure cluster quality. The silhouette score is a common metric that works for both algorithms.
from sklearn.metrics import silhouette_score

# labels should come from a clustering model fitted to X_scaled
score = silhouette_score(X_scaled, labels)
print(score)
The silhouette score ranges from -1 to 1. Values near 1 indicate that points are well matched to their own cluster and poorly matched to neighboring clusters. A negative value suggests that points may be assigned to the wrong cluster.
For KMeans, you can also use the elbow method on inertia_ to pick n_clusters. For DBSCAN, you can vary eps and evaluate the silhouette score on the resulting labels, ignoring noise points if necessary. Keep in mind that silhouette score can be misleading when clusters are non-convex or have complex shapes, so it may not reflect the true quality of DBSCAN results.
Performance and Scalability Considerations
KMeans is generally faster than DBSCAN on large datasets. Its time complexity is O(n·k·d·i), where n is the number of points, k is the number of clusters, d is the number of features, and i is the number of iterations. DBSCAN without a spatial index has O(n²) worst-case complexity, though scikit-learn can use a ball tree or KD tree to reduce this to O(n log n) for low-dimensional data.
Memory usage also differs. KMeans stores only the centroids and labels, while DBSCAN may need to store a full distance matrix if you use a precomputed distance matrix. For very large datasets, KMeans is often the only practical choice unless you can subsample or use a spatial index.
As the number of dimensions increases, distances become less informative and a global eps becomes harder to interpret. In high-dimensional spaces, you may need to use a different distance metric or reduce dimensionality first. KMeans also suffers from the curse of dimensionality, but it does not require tuning a neighborhood radius.
Common Pitfalls and Edge Cases
One frequent mistake with KMeans is using it on data with significant outliers. Because KMeans minimizes squared distances, a single outlier can pull a centroid far away from the actual cluster. If your data has outliers, consider using DBSCAN or removing the outliers first.
With DBSCAN, a common issue is choosing an eps that is too small or too large. A small eps leads to many noise points, while a large eps merges distinct clusters. The k-distance plot helps, but it is not always unambiguous. Also, DBSCAN struggles with clusters of very different densities. A single global eps cannot capture both dense and sparse regions simultaneously. In such cases, you might need to use a variant like OPTICS or apply DBSCAN separately to different regions.
Another edge case is duplicate points. DBSCAN treats duplicates as part of the same neighborhood, which can affect the density calculation. KMeans is not immune to duplicates: they add weight to those locations when centroids are computed. If duplicates are not meaningful, remove them before clustering.
Finally, remember that both algorithms are sensitive to the distance metric. By default, scikit-learn uses Euclidean distance. If your data requires a different metric, such as Manhattan or cosine, you can pass the metric parameter to DBSCAN. In scikit-learn, KMeans uses Euclidean distance and does not accept a metric parameter, because it relies on mean computations. This is another reason to choose DBSCAN when your domain requires a non-Euclidean distance.