Python Variable Assignment: Names, References, and Mutability
Understand how Python variable assignment binds names to objects, why rebinding differs from mutation, and how aliasing affects real code.
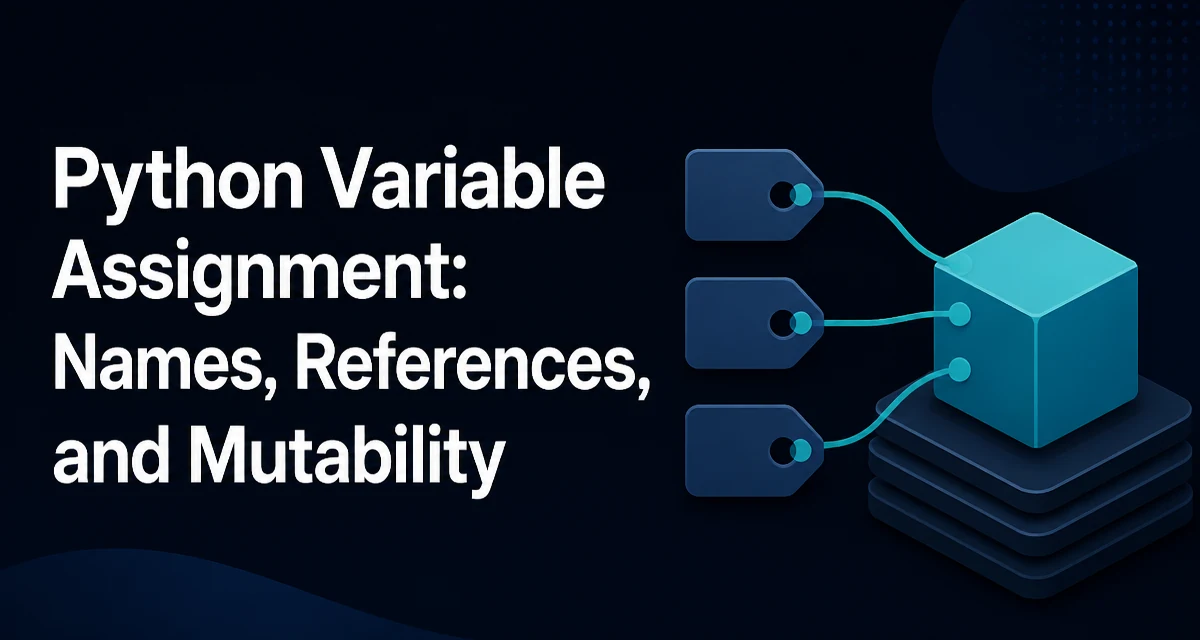
Python variable assignment is often described as "putting a value into a variable," but that mental model breaks down quickly in real code. In Python, x = 5 does not store the integer 5 inside a slot named x. It binds the name x to an object that already exists in memory. That distinction matters for debugging, for designing APIs, and for understanding why some code behaves differently than it looks.
What Python Variable Assignment Actually Does
When you write:
x = [1, 2, 3]Python evaluates the right-hand side first, producing a list object. It then binds the name x in the current namespace to that object. The variable is a reference, not a container. The list object itself lives on the heap, and x is just a label pointing at it.
This is fundamentally different from languages like C or Java with primitive types, where a variable holds the value directly. In Python, every assignment is a reference assignment. Even integers follow this rule:
a = 1000
b = a
Here a and b both reference the same integer object. No copy is made. If you later rebind a:
a = 2000b still references the original 1000 object. Rebinding a does not change what b points to.
Rebinding Versus Mutation
The most common source of confusion is the difference between rebinding a name and mutating an object.
items = [1, 2, 3]
items = [4, 5, 6] # rebinding: items now points to a new listitems = [1, 2, 3]
items.append(4) # mutation: the same list object is modifiedRebinding changes which object the name points to. Mutation changes the object itself. The distinction matters because other names may reference the same object. If you mutate, every name pointing at that object sees the change. If you rebind, only the rebound name is affected.
This distinction is central to debugging. When a list changes unexpectedly, the first question is whether some code path mutated it in place or rebound the name. Trace the object identity, not just the variable name.
How Immutable Types Change the Picture
Immutable types such as int, str, tuple, and frozenset cannot be modified after creation. Operations that appear to modify them actually create new objects.
s = "hello"
s = s + " world"
The second line creates a new string object and rebinds s to it. The original string is unchanged and becomes eligible for garbage collection. This is why string concatenation in a loop is slow: each iteration creates a new string object, and the old one is discarded.
Tuples behave the same way. A tuple cannot be mutated, but if it contains a mutable object, that object can still change:
t = ([1, 2], "fixed")
t[0].append(3)  # valid: the list inside the tuple is mutated
The tuple itself is immutable, but the list it references is not. This means a tuple containing a list is not hashable, so it cannot be used as a dictionary key or set element.
Aliasing: When Two Names Share One Object
Aliasing occurs when two or more names reference the same object. This is common and often intentional, but it can produce surprising behavior.
original = [1, 2, 3]
copy = original
copy.append(4)

print(original)  # [1, 2, 3, 4]
The copy name was not a copy at all. Both names reference the same list. To create an independent list, you need list(original), original.copy(), or original[:]. The same applies to dictionaries and sets.
This is not a bug in Python. It is the intended reference semantics. The problem arises when developers expect value semantics without explicitly requesting them.
The Default Argument Trap
Function default arguments are evaluated once, at function definition time, not on each call. If the default is a mutable object, every call that does not supply the argument shares the same object.
def add_item(item, container=[]):
    container.append(item)
    return container

add_item("a")  # ['a']
add_item("b")  # ['a', 'b']
The second call returns ['a', 'b'] even though the caller expected a fresh list. The default list persists across calls because it is bound once when the function is defined.
The standard fix is to use None as the default and create a new object inside the function:
def add_item(item, container=None):
    if container is None:
        container = []
    container.append(item)
    return container
This avoids the shared mutable default and makes the function's behavior predictable.
Assignment in Loops and Closures
Loop variables are rebound on each iteration, but closures capture variables by reference, not by value. This creates the classic late-binding problem:
funcs = []
for i in range(3):
    funcs.append(lambda: i)

for f in funcs:
    print(f())  # 2 2 2
All three lambdas reference the same i variable, which ends at 2 after the loop completes. The fix is to capture the current value by binding it as a default argument:
funcs = []
for i in range(3):
    funcs.append(lambda x=i: x)
Now each lambda has its own default value, so the output is 0 1 2.
Choosing Between Rebinding and Mutation
The choice between rebinding and mutation affects readability and maintainability. Rebinding is generally safer because it does not affect other references. Mutation is useful when you want to share state deliberately, such as in a cache or a shared configuration object.
A practical rule: prefer rebinding when the variable represents a value that could be replaced, and prefer mutation when the variable represents a collection that is shared and expected to grow or shrink. If you are unsure whether other code holds a reference to the object, rebinding is the safer default.
This distinction also affects performance in some cases. Mutating a large list in place avoids allocating a new list, but the difference is rarely significant unless the list is very large or the operation is in a hot loop. The maintainability benefit of clear semantics usually outweighs micro-optimizations.
Try matching browser tools
All toolsSmall utilities that fit Python work — they run entirely in this browser tab, so nothing you paste leaves your device.
Related Python guides
All Python guidesPython iter(): How the Built-in Function Works
Explains Python's iter() built-in: how it creates iterators, the two-argument sentinel form, custom iterator classes, and common edge cases.
Python Pika: Queues, Exchanges, Routing Keys, and Acknowledgements
Learn how to use Python's Pika client with RabbitMQ: declare queues and exchanges, publish with routing keys, consume messages, and handle acknowledgements reliably.
Python Kafka: kafka-python vs Confluent Client
python kafka python vs confluent kafka: Compare kafka-python and Confluent Kafka Python clients: API differences, performance, feature coverage, and when to choose eac...
Python Kafka Offsets, Partitions, and Manual Commits
Learn how Kafka offsets and partitions work and how to manually commit offsets in Python consumers with kafka-python and confluent-kafka. Covers sync vs async commits, rebalances, and seeking.
More in Python
All Python guidesThe guides filed next to this one in Python, in library order.