Python zip vs enumerate: When to Use Each
Learn when to use Python's zip and enumerate for parallel iteration and indexed loops, with practical examples and performance insights.
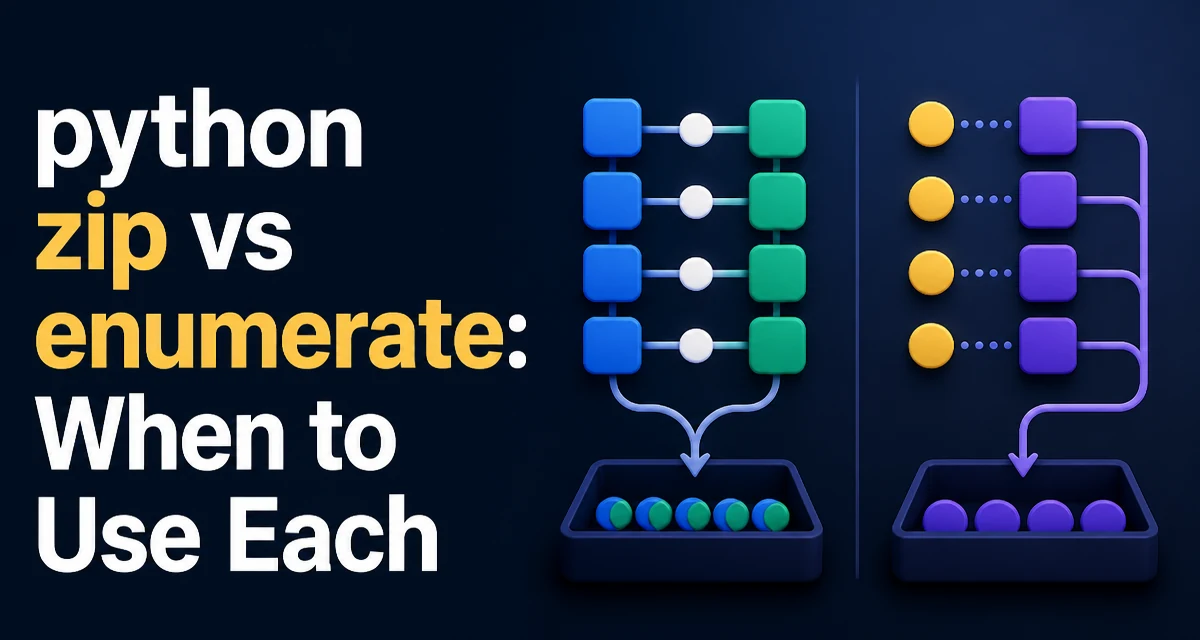
When you need to iterate over sequences in Python, zip and enumerate are two built-in functions that often come up. The question of which to use comes down to what you need from the iteration: pairing elements from separate iterables, or tracking the index of each element as you go. Both are efficient and idiomatic, but they serve different purposes.
How zip Works
zip accepts multiple iterables and returns an iterator that yields tuples, each containing one element from every input iterable. The iteration stops when the shortest input is exhausted. This makes it ideal for processing parallel data sets of equal length, or when you want to truncate to the shortest sequence.
names = ["Alice", "Bob", "Charlie"]
scores = [85, 92, 78]

for name, score in zip(names, scores):
    print(f"{name}: {score}")
This pairs each name with its corresponding score. If one list is longer, the extra elements are ignored.
How enumerate Works
enumerate adds an automatic counter to an iterable. It yields pairs of (index, element), where the index starts at 0 by default. This is useful when you need to know the position of an item while iterating, such as when modifying a list in place or referencing an index-based data structure.
items = ["apple", "banana", "cherry"]

for i, item in enumerate(items):
    print(f"{i}: {item}")
You can also specify a custom starting index with the start parameter:
for i, item in enumerate(items, start=1):
    print(f"{i}. {item}")
Key Differences Between zip and enumerate
| Aspect | zip | enumerate |
|---|---|---|
| Primary purpose | Pair elements from multiple iterables | Add an index to a single iterable |
| Output | Tuples of elements from each iterable | Tuples of (index, element) |
| Number of iterables | One or more (usually two or more) | Exactly one |
| Stops when | Shortest input is exhausted | The single iterable is exhausted |
| Typical use | Parallel iteration, matrix transposition | Indexed access, line numbering |
When to Use zip
Use zip when you have multiple sequences that need to be processed together. Common scenarios include merging data from separate lists, transposing a matrix represented as a list of rows, or iterating over two related collections simultaneously.
For example, if you have a list of keys and a list of values, zip can combine them into a dictionary:
keys = ["name", "age", "city"]
values = ["Alice", 30, "Paris"]

person = dict(zip(keys, values))
zip is also useful for grouping elements from multiple sources, such as reading two files line by line.
When to Use enumerate
Use enumerate when you need the index of each element during iteration. This is common when you want to update a list at specific positions, compare an element with its neighbors, or generate output that includes a line number.
lines = ["first", "second", "third"]

for i, line in enumerate(lines):
    if i % 2 == 0:
        print(f"Even line {i}: {line}")
It also simplifies code that would otherwise require a manual counter variable, reducing the chance of off-by-one errors.
Performance and Memory Considerations
Both zip and enumerate return iterators, meaning they generate values lazily. No large intermediate list is created, so memory usage is constant relative to the input size. The per-iteration overhead is small: both produce a tuple for each yielded item. In practice, the performance difference between the two is negligible for most workloads.
If you need to materialize the results, you can wrap them in list() or dict(), but that consumes memory proportional to the input length. For streaming or large data, prefer the iterator form.
Common Mistakes and Edge Cases
One common mistake is assuming zip requires equal-length inputs. It does not; it silently stops at the shortest. If you need to pad shorter iterables, use itertools.zip_longest instead.
Another edge case is using enumerate with a start value that is not an integer. The start parameter should be an integer; passing a float, for example, raises a TypeError. Also, enumerate works on any iterable, including generators, but the index reflects the order in which items are produced.
Combining zip and enumerate
Sometimes you need both the index and paired elements from multiple iterables. You can nest them:
list1 = ["a", "b", "c"]
list2 = [1, 2, 3]

for i, (x, y) in enumerate(zip(list1, list2)):
    print(f"Pair {i}: {x} -> {y}")
This pattern is concise and readable. The outer enumerate provides the position, while the inner zip handles the parallel pairing.
Choosing Based on Your Data Shape
The decision between zip and enumerate comes down to the structure of your data. If you have multiple sequences that must be aligned by position, zip is the natural choice. If you have a single sequence and need to know each element's index, enumerate is more direct. In cases where both are needed, combining them as shown above gives you full control without introducing manual counters or index variables.
Both functions are fundamental to writing clean, Pythonic loops. Understanding their distinct roles helps you avoid unnecessary complexity and keeps your code readable and maintainable.
Try matching browser tools
All toolsSmall utilities that fit Python work — they run entirely in this browser tab, so nothing you paste leaves your device.
Related Python guides
All Python guidesPython iter(): How the Built-in Function Works
Explains Python's iter() built-in: how it creates iterators, the two-argument sentinel form, custom iterator classes, and common edge cases.
Python Pika: Queues, Exchanges, Routing Keys, and Acknowledgements
Learn how to use Python's Pika client with RabbitMQ: declare queues and exchanges, publish with routing keys, consume messages, and handle acknowledgements reliably.
Python Kafka: kafka-python vs Confluent Client
python kafka python vs confluent kafka: Compare kafka-python and Confluent Kafka Python clients: API differences, performance, feature coverage, and when to choose eac...
Python Kafka Offsets, Partitions, and Manual Commits
Learn how Kafka offsets and partitions work and how to manually commit offsets in Python consumers with kafka-python and confluent-kafka. Covers sync vs async commits, rebalances, and seeking.
More in Python
All Python guidesThe guides filed next to this one in Python, in library order.