Linux Text Processing: grep, sed, and awk Command Pipelines
Select, reshape, aggregate: the three-stage pipeline that turns raw logs into counts, with the regex, in-place edit and field-separator traps spelled out.
Quick Summary
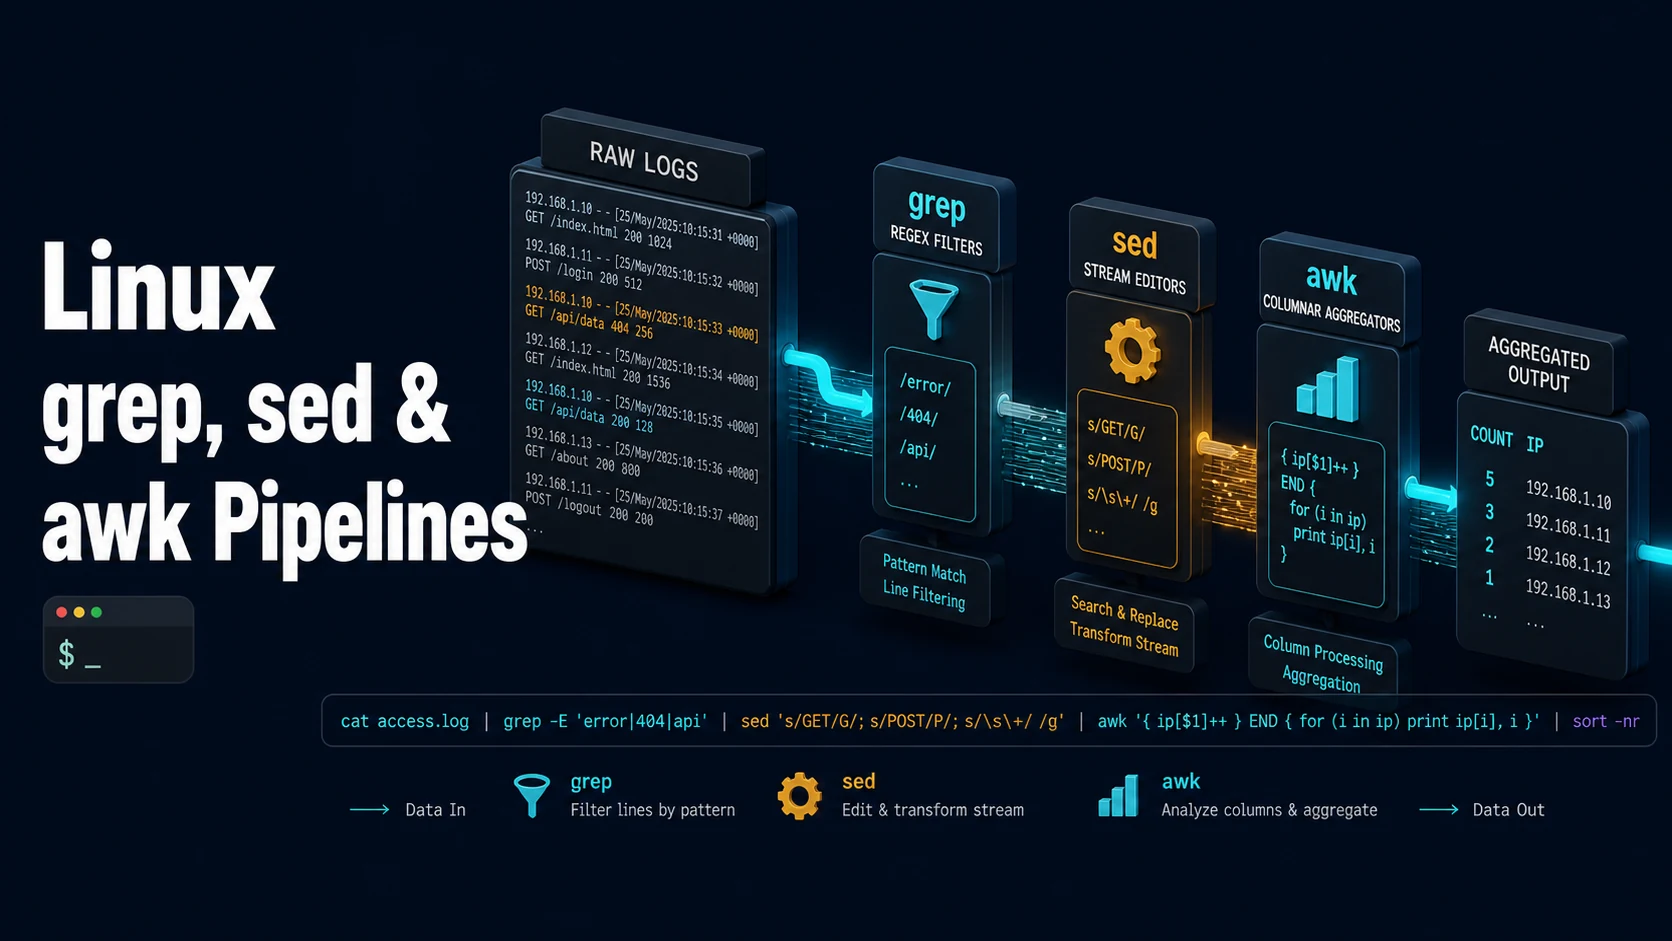
grep selects lines, sed edits a stream of them, and awk turns them into fields and records. Each one is a complete tool on its own, but the reason they are taught together is that a real log analysis is one pipeline: filter the noisy lines, reshape what is left, then aggregate by column.
grep answers "which lines contain this pattern". sed 's/old/new/g' answers "change this pattern everywhere on a line". awk '{sum += $5} END {print sum}' answers "what is the total of column five". The operator that connects them is the pipe, and each tool's output format is the next tool's input format: plain lines, one record per line, columns separated by whitespace or a chosen delimiter.
The traps are consistent too. grep without -F treats the pattern as a regex, so . and * match more than intended. sed -i overwrites a file with no backup unless you pass an extension. awk splits on runs of whitespace when no -F is given, so a CSV needs -F, and a tab-separated log needs -F'\t' explicitly.
Basic Syntax & Signature
# grep: pattern selection
grep -n "ERROR" app.log              # line numbers
grep -i -c "timeout" app.log         # case-insensitive count
grep -v "^#" /etc/ssh/sshd_config     # drop comment lines
grep -A3 -B2 "panic" app.log         # context around matches
grep -oE '[0-9]{1,3}(\.[0-9]{1,3}){3}' access.log   # extract just the IPs
grep -rl "TODO" src/                  # files containing the pattern
grep -E '^(ERROR|FATAL)\b' app.log    # extended regex alternation

# sed: line-oriented substitution and deletion
sed -n '10,20p' file.txt              # print a range, no duplicates
sed -e 's/\.json$/\.yaml/' -e 's/"true"/true/g' config.txt
sed -i.bak 's/localhost/127.0.0.1/g' app.conf   # in place, keep a backup
sed '/^$/d' file.txt                  # delete empty lines
sed -n '/BEGIN/,/END/p' file.txt      # a block between two markers

# awk: fields and aggregation
awk '{print $1, $(NF-1)}' access.log
awk -F, 'NR > 1 { sum += $3 } END { printf "%.2f\n", sum }' sales.csv
awk '$9 == 500 { c++ } END { print c + 0 }' access.log
awk -F'\t' '{ seen[$2]++ } END { for (k in seen) print seen[k], k }' data.tsv | sort -rn
The three combine without quoting games as long as each stage is a separate single-quoted argument:
grep -v 'healthcheck' access.log |
  awk '$9 >= 500 { print $1, $7 }' |
  sort | uniq -c | sort -rn |
  head -20
Key Comparison Table
| Need | Tool | Idiom |
|---|---|---|
| Lines matching a pattern | grep | grep -E 'pat' f |
| Lines not matching | grep | grep -v 'pat' f |
| Replace within lines | sed | sed 's/a/b/g' |
| Delete lines by pattern | sed | sed '/pat/d' |
| Print a line range | sed | sed -n '5,15p' |
| Extract a column | awk | awk '{print $3}' |
| Sum a column | awk | awk '{s+=$3} END{print s}' |
| Count by key | awk + sort | `awk '{c[$1]++} END{for(k in c) print c[k],k}' |
| Filter by numeric field | awk | awk '$9 > 400' |
| Join two files on a key | awk | awk 'NR==FNR{a[$1]=$2;next} $1 in a{print $0,a[$1]}' f1 f2 |
| Deduplicate | sort -u | sort -u |
| Count duplicates | `sort | uniq -c` |
Practical Edge Cases & Deep Dives
1. Regex versus fixed string, and the exit code
grep 'v1.2' versions.txt        # '.' matches any character: also finds v1x2
grep -F 'v1.2' versions.txt     # fixed string, literal dot
grep -F -q 'ready' health.txt && echo "ready" || echo "not ready"
grep -c 'ERROR' app.log; echo "exit=$?"
grep exits 0 when a match is found, 1 when nothing matched, and 2 on error. In a script with set -e, grep returning 1 aborts the script even though "no matches" is a normal outcome — the fix is grep -q ... || true, or an explicit if. This is one of the most common reasons a deploy script stops on a log that simply had no errors.
2. Extracting fields without awk
# Cut by character or delimiter
cut -d: -f1,3 /etc/passwd
cut -c1-19 app.log

# awk when fields are uneven, cut when the delimiter is exact
awk '{print $1}' file
awk -F'[][]' '{print $2}' file   # split on both '[' and ']'
cut cannot handle a variable number of spaces, and awk with the default separator collapses runs of whitespace, which is why awk '{print $1}' works on ps output while cut -d' ' -f1 does not.
3. In-place edits that are safe to re-run
# Idempotent: only replaces the exact uncommented line.
sed -i.bak -E 's/^#?PermitRootLogin .*/PermitRootLogin no/' /etc/ssh/sshd_config

# Anchored to the start of the line: will not touch a comment that mentions the key.
sed -i -E 's/^Listen 80$/Listen 8080/' /etc/httpd/conf/httpd.conf

# Verify before writing: print what would change.
sed -E 's/^Port 22$/Port 2222/' sshd_config | diff - sshd_config
sed -i truncates and rewrites the file, which breaks hard links and drops the inode's original permissions on some platforms; -i.bak keeps the original next to it. GNU sed and BSD/macOS sed disagree on -i: the BSD form requires an argument (-i '' for no backup), so scripts that run on both need a guard.
4. Aggregation: top talkers from a log
# Top 10 client IPs by request count, excluding bots
awk '$9 == 200 { print $1 }' access.log |
  grep -v -E '^(10\.|192\.168\.)' |
  sort | uniq -c | sort -rn | head -10

# Status code distribution with percentages
awk '{ c[$9]++; total++ } END { for (s in c) printf "%s %6d %5.1f%%\n", s, c[s], 100*c[s]/total }' access.log |
  sort -k2 -rn

# Bytes per path, human readable
awk '{ b[$7] += $10 } END { for (p in b) printf "%12d %s\n", b[p], p }' access.log |
  sort -rn | head -5 | numfmt --to=iec
NR is the record number, NF the field count, $NF the last field, and $(NF-1) the one before it — which is how you read a log line whose trailing fields vary. END blocks run once, after the last record, and are where all aggregation belongs.
5. Joining two files on a key
# users.csv: id,name   orders.csv: id,total
awk -F, 'NR == FNR { name[$1] = $2; next } $1 in name { print name[$1], $2 }' users.csv orders.csv

# FNR resets per file, NR does not: the classic "first file only" trick.
awk 'FNR == 1 { print FILENAME }' *.log
NR == FNR is true only while awk is reading the first file, so the first block builds a lookup table and the second block joins against it. Reading the smaller file first keeps the table in memory.
6. Locale and encoding surprises
LC_ALL=C grep -c 'error' huge.log        # byte-wise, far faster on ASCII logs
LC_ALL=C sort bad.csv                    # deterministic byte order
grep -a 'pattern' binary.log             # treat a binary file as text
iconv -f latin1 -t utf-8 export.csv | awk -F, '{print $2}'
In a UTF-8 locale, grep and sort decode characters, which is correct for text and slow for gigabytes of ASCII. LC_ALL=C takes the byte path. grep also prints "Binary file matches" instead of the line when it detects a NUL byte, which is why a log with a stray binary blob appears to have no matches until -a is added.
7. Driving control flow with grep -q
if grep -q 'ALREADY_CONFIGURED' /etc/app/state; then
  echo "skipping"
else
  configure
fi

# -q stops at the first match: the fast path on gigabyte files
grep -q -F 'stack trace' crash.log

# Counting matches without parsing output
if [ "$(grep -c 'ERROR' app.log)" -gt 100 ]; then alert; fi

# -m limits work when only presence matters
grep -m 1 'ready' startup.log
grep -q exits as soon as it finds a match and writes nothing, which is why it belongs in conditions rather than grep ... > /dev/null. grep -c prints 0 and exits 1 when there are no matches, so a script that compares the count must not rely on the exit status at the same time — pick one mechanism per check.
Common Compilation/Runtime Mistakes
| Symptom | Cause | Fix |
|---|---|---|
| Pattern matches too much | Unescaped regex metacharacters | grep -F or escape them |
| Script aborts on no match | grep exits 1 under set -e | ` |
sed -i wipes the file on macOS | BSD requires an argument to -i | sed -i '' ... |
sed replacement does nothing | . or $ in the pattern | Anchor with ^...$ |
awk prints the whole line | Missing -F on a delimited file | -F, or -F'\t' |
uniq counts nothing | Input not sorted | sort before uniq |
| Column off by one | Leading whitespace shifts fields | awk -F'\\s+' or trim first |
| Numbers sort as text | sort without -n | sort -rn |
| Binary file matches | NUL bytes in the stream | grep -a |
| Slow on large files | UTF-8 locale decoding | LC_ALL=C |
\$ expanded by the shell | Double quotes around the script | Single-quote awk and sed |
The pipeline shape — select, reshape, aggregate — is worth internalising because it maps onto grep, sed, awk, and sort exactly. When a one-liner starts needing three sed expressions and a variable, the honest move is to switch to an awk block, where all three stages happen in one pass with named fields instead of accumulating quotes.
Try matching browser tools
All toolsSmall utilities that fit Linux work — they run entirely in this browser tab, so nothing you paste leaves your device.
Related Linux guides
All Linux guidesBash Indexed Arrays, Associative Maps, and Parameter Expansion
Quoting decides whether an array stays a list, and the expansion operators replace most external text tools. Includes set -u, mapfile, namerefs, and the bash 3.2 differences that break scripts on macOS.
Parsing JSON and YAML in Shell Pipelines with jq and yq
jq is a filter language, not a pretty-printer. The operators that do the work, --arg versus string interpolation, in-place YAML edits, and how to tell which yq is installed before writing a command.
Linux Memory, Swap, the OOM Killer, vmstat, and sysctl Tuning
MemAvailable versus used, the vmstat columns that prove thrashing, how the OOM killer picks its victim, and the sysctl keys that belong in /etc/sysctl.d instead of a one-off command.
Linux Firewalls: ufw, iptables, and nftables Rules and Persistence
First-match ordering, stateful filtering, and persistence: the three ideas behind every Linux firewall. Plus why Docker-published ports ignore ufw and how DOCKER-USER closes them.
More in Linux
All Linux guidesThe guides filed next to this one in Linux, in library order.